
Google Vertex AI
VerifiedGoogle Cloud's unified platform for building, tuning, and deploying AI models
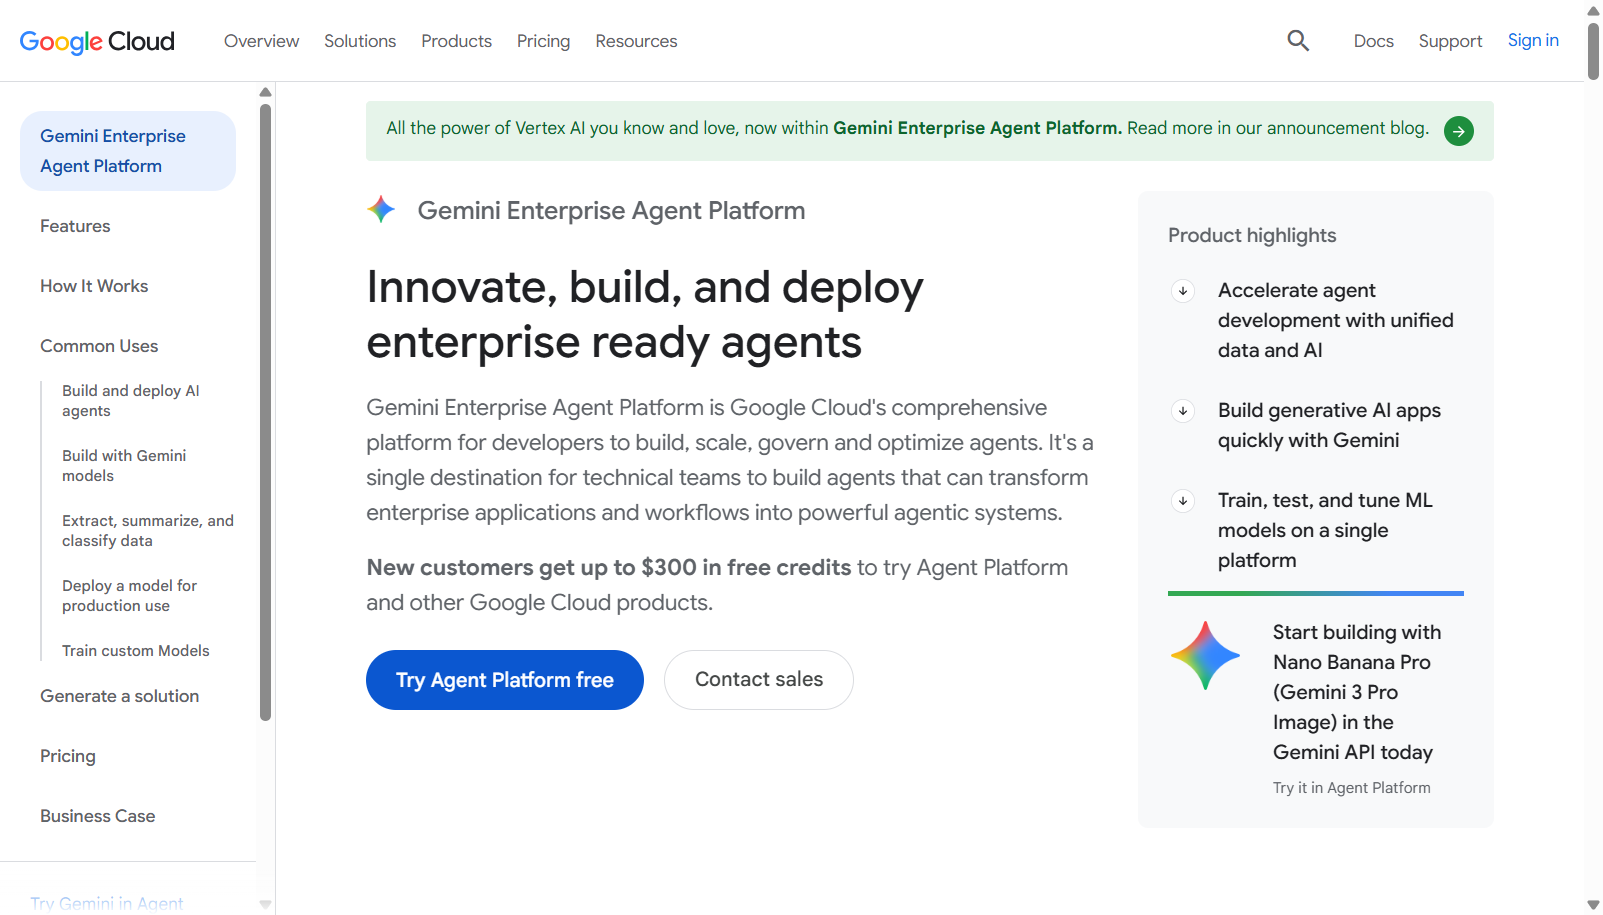 See all screenshots
- Deployment Cloud Based
- Starting price $0.25 / $1.50 per 1M tokens (text)
- Free trial Available
- Best for Startups, SMEs, Agencies
What is Google Vertex AI?
Google Vertex AI is Google Cloud's unified platform for discovering, customizing, and deploying AI models. Its Model Garden catalogs more than 130 models, including Google's own Gemini family alongside partner and open-source models, and supports fine-tuning, evaluation, and one-click deployment for both generative AI and classical machine learning workloads.
Generative AI usage is billed per million input and output tokens, with rates that vary by model, and cheaper batch and context-caching options for non-time-sensitive or repeated workloads. New Google Cloud accounts receive $300 in credit valid for 90 days. Vertex AI also includes Agent Builder, RAG tooling, model monitoring, and enterprise security controls such as IAM and VPC Service Controls.
Key Features of Google Vertex AI
Google Vertex AI lists 9 documented features, including Model Garden with 130+ foundation models from Google, partners, and open source, Access to the Gemini model family plus third-party models and Fine-tuning and customization of foundation models. The list below covers what the product does rather than how it is marketed.
- Model Garden with 130+ foundation models from Google, partners, and open source
- Access to the Gemini model family plus third-party models
- Fine-tuning and customization of foundation models
- RAG tooling and Vertex AI Search for grounding models on enterprise data
- AutoML, custom training, and pipelines for classical ML
- Model monitoring and evaluation tools
- Agent Builder for creating and deploying AI agents
- Batch and provisioned throughput pricing options
- Enterprise IAM and VPC Service Controls integration
Google Vertex AI Pricing
Google Vertex AI lists 5 plans. One is free; the rest are quoted on request.
Gemini 2.5 Flash-Lite
$0.25 / $1.50 per 1M tokens (text)
Input / output per million tokens
Cheapest tier text model
Gemini 2.5 Flash
$0.30 / $2.50 per 1M tokens (text)
Input / output per million tokens
Mid-tier model
Gemini 2.5 Pro
$1.25-$2.50 / $10-$15 per 1M tokens
Higher rate applies above 200K input tokens
Flagship model
Batch/Flex
~50% discount off standard pricing
Asynchronous workloads
For non-time-sensitive requests
Google Vertex AI Specifications
Google Vertex AI is available on web app. It offers an API and has a free trial.
- Deployment
- Cloud Based
- Billing cycle
- Monthly
- Desktop
- Web App
- Languages
- English
- Built for
- Startups
- SMEs
- Agencies
- Enterprises
- Support
- Phone
- Tickets
- Training
- Integrations
- Google Workspace, BigQuery, Google Kubernetes Engine, LangChain, Hugging Face, and other Google Cloud services
- Public API
- Yes
- Free trial
- Yes
- Free plan
- No
- Runs in browser
- Yes
- Customisable
- Yes
- Website
- cloud.google.com
Google Vertex AI Videos
Google Vertex AI Screenshots
Google Vertex AI Comparisons


Google Vertex AI Reviews
No reviews yet
Used Google Vertex AI? Share your experience and help other buyers decide.
Google Vertex AI FAQs
Alternatives to Google Vertex AI
Other AI Development Platform recorded on the same fields.